One server cannot hold the peak
Every request hits the same machine. CPU and connections top out, and extra machines never see the traffic.
Adding a machine mid-event does not save the day
Solutions Technical solutions Load balancing
Distribution, health checks, and node scaling
What fails first as traffic grows is rarely one machine running out of power. It is every request landing on that one machine. Requests meet a single entry, then go out to healthy backend nodes.
Size the nodes from peak concurrency
Take single points, bottlenecks, and downtime out of the architecture.
Every request hits the same machine. CPU and connections top out, and extra machines never see the traffic.
Adding a machine mid-event does not save the day
When the entry and the application share one machine, a hardware fault or a crashed process takes the site offline.
One hardware fault is a full outage
Changing the architecture means a late-night outage. After a node switch, logins disappear and carts can be emptied.
Scaling waits for dawn and hopes sessions survive
Sending all traffic back to one region detours distant users. Buying bandwidth in every region stacks the cost.
Distant users stay slow, and bandwidth is paid twice
Peaks, logins, many regions, and releases without downtime all need the entry split from the backends.
Typical case
A short burst fills one machine, and a machine added mid-event never receives requests.
How to size it
Split the entry from the backends. Add nodes for the peak, then remove them when the campaign ends.
Typical case
The entry and the application share one machine, so one fault takes the site offline.
How to size it
A failed health check removes that node. The remaining healthy nodes keep the traffic.
Typical case
A node switch drops the login and can empty the cart.
How to size it
Sticky sessions keep one user on one node, with cluster session sync beside them.
Typical case
All traffic returns to one region. Distant users detour, and regional bandwidth stacks up.
How to size it
Each data center takes nearby users. Backend groups grow sideways by region.
Typical case
Short and long connections pile up, and one machine hits its connection ceiling first.
How to size it
Databases and long connections use Layer 4. HTTP APIs use Layer 7. Add another node when the group is full.
Typical case
A new version needs downtime, and a problem means rolling the whole site back.
How to size it
Put the new version on part of the group and shift a share of traffic. On a problem, send traffic back to the old nodes.
Health checks decide who receives traffic. Failed nodes drop out, canary traffic moves by share, and sessions stay in sync.
Entry, backend, and hardening are sized on different terms.
Entry, backend, and hardening are chosen separately. Specs and prices follow the product page.
| Role / model | CPU | Memory | Disk | Line | Bandwidth | Defense | IPv4 | From | Order |
|---|---|---|---|---|---|---|---|---|---|
| US-E3-1230v3 | E3-1230V3·4C / 8T | 32G | 1T SSD | CN2 Direct Pro | 30M / 不限流量 | 10G | 3 IPs | $79 /mo | Order |
| HK-E3-1230V3 | E3-1230V3·4C / 8T | 32G | 1T SSD | CN2 Direct Pro | 10M / 不限流量 | 20G | 3 IPs | $89 /mo | Order |
| US-LA-E5-2620 | E5-2620·6C / 12T | 32G | 1T HDD | China Direct Pro | 100M / 不限流量 | 10G | 5 IPs | $99 /mo | Order |
| US-E5-2630x2 | E5-2630 x 2·12C / 24T | 32G | 1T SSD | CN2 Direct Pro | 30M / 不限流量 | 10G | 3 IPs | $109 /mo | Order |
The entry is sized by forwarding rules and the connection table. Backends scale out with concurrency. Hardening stays on the public entry that is actually exposed.
Prices follow the product page. CPU, memory, and disk not listed can be configured. Quarterly 5% off, half-year 10% off, yearly 15% off, and renewals use the same price.
Nodes = peak concurrency ÷ connections per node, plus spare capacity. Probe settings follow the pool size.
| Peak connections | Backend nodes 1,000 connections each | Backend nodes 2,000 connections each | max_fails / fail_timeout | Session persistence |
|---|---|---|---|---|
| 500 | 2 | 2 | 1 / 10s (default) | ip_hash |
| 1,000 | 2 | 2 | 1 / 10s (default) | sticky cookie |
| 5,000 | 6 | 4 | 2 / 10s | sticky cookie |
| 10,000 | 11 | 6 | 2 / 10s | sticky learn |
| 50,000 | 51 | 26 | 3 / 15s | sticky learn |
| 100,000 | 101 | 51 | 3 / 15s | sticky learn + slow_start |
| 200,000 | 201 | 101 | 3 / 15s | sticky learn + slow_start |
Nodes = peak concurrency ÷ connections per node, rounded up, plus 1. At 5,000 connections and 1,000 per node, 5,000 ÷ 1,000 = 5, plus 1 spare is 6. At 2,000 per node, 5,000 ÷ 2,000 rounds up to 3, plus 1 is 4. 1,000 and 2,000 are planning figures, not the NGINX default. max_conns defaults to 0, which means unlimited, and should match what one machine can actually hold.
| Setting | Default | What it controls | Common mistake |
|---|---|---|---|
| max_fails | 1 | Failures inside fail_timeout before a node is marked down | Ignored when the pool has only one server |
| fail_timeout | 10s | Window for counting failures, and how long a node stays down | 10 seconds is too sharp when the network jitters, so nodes flap |
| slow_start | 0 (off) | How long a recovered node's weight climbs from 0 to its set value | Without it, a recovered node is flooded at once |
| max_conns | 0 (unlimited) | Maximum active connections on one backend | Without it, one node can be crushed |
| queue timeout | 60s | How long a request waits when no upstream is free; then 502 | A long queue turns 502s into a pile-up |
| Consistent hash | Layer 4 only | Adding or removing a backend remaps only a few keys | Layer 7 does not support it, so a scale-out drops the cache together |
| sticky learn session store | 1 MB zone ≈ 4,000 sessions | Sessions sit in shared memory on 64-bit platforms | A growing store evicts older sessions |
| sticky session timeout | 10 minutes | A session with no further visits is removed | A long mobile session is treated as a new one |
| backup | unmarked (off) | Takes traffic only when every primary server is down | Using the spare as a second everyday pool |
| down / drain | unmarked (off) | down removes it; drain only finishes requests already bound | Deleting a server for a short removal remaps every hash |
Two traps: with only one server in the pool, max_fails, fail_timeout, and slow_start are ignored, so that server is never marked down. Consistent hash is Layer 4 only. A cache backend on Layer 7 loses the cache together each time you scale out.
Scheduling, removal, sessions, canary release, and node changes, each with a deliverable practice.
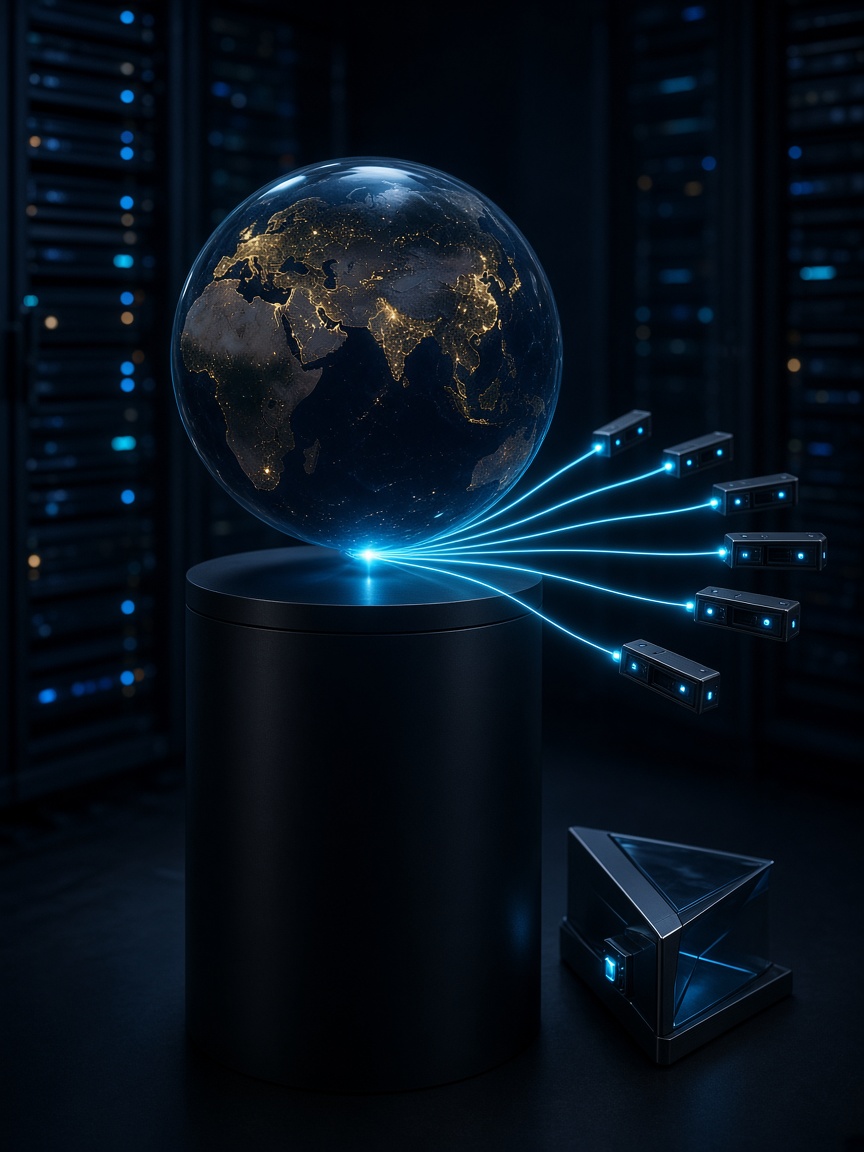
Requests reach one entry first. Layer 4 forwards connections. Layer 7 splits by domain and URL. Health checks remove failed nodes, sticky sessions work with cluster sync, and a canary shifts only part of the traffic. Nodes change with peak concurrency. The entry config stays.
Layer 4 forwards TCP connections for databases, long connections, and non-HTTP protocols. Layer 7 routes HTTP by domain and URL.
What it means for traffic scheduling: The right layer means the architecture does not have to be rebuilt later.
A failed check isolates that node, and new requests stop going there. When it recovers, it rejoins the group.
What it means for traffic scheduling: One failed machine is no longer a full outage.
One user stays on one node, with cluster session sync. Logins remain when nodes are added or removed.
What it means for traffic scheduling: Scaling no longer clears the cart or the login.
The new version lands on part of the group and receives a small share first. On a problem, traffic returns to the old nodes.
What it means for traffic scheduling: Rollback does not need a redeploy, and the service stays up.
Add backend nodes sideways for the new traffic. The entry and the policy stay. After the peak, take nodes out of the group.
What it means for traffic scheduling: Scaling does not wait for dawn and does not replace the architecture.
After launch, the policy and the node count can still follow the peak.
First reply within 30 minutes on workdays. Nights and weekends cover outages only.
A standard setup is delivered in 30 to 60 minutes. A custom setup takes 1 to 2 workdays.
Covers the United States, Hong Kong, Japan, Singapore, Germany, and 12 or more regions in total.
We help set listeners, forwarding policy, and health checks. Parameters follow your peak, not a copied default.
Raid arrays and live data-center backup mean one disk failure does not stop the service.
Network availability targets 99.9 percent. Bandwidth and backend nodes can change with the business.
How many backend servers, which protocols, how far daily traffic sits from the peak, where users are, and whether releases must stay online — share these and we will suggest the scheduling setup and a price.
Usually no. The load balancer sits at the entry. Backends only listen on the right port and join over the private network. If the application keeps session files on local disk, say so while we scope the plan.
The site does not go down as a whole. A failed check isolates that node, new requests stop landing there, and other healthy nodes keep serving. When it recovers, it rejoins the group.
Sticky sessions keep one user on one node. With cluster session sync, logins stay when nodes change. Existing users are unaffected. New users are placed in the group that includes the new nodes.
It depends on the protocol and how fine the split must be. Layer 4 forwards TCP connections for databases, long connections, and non-HTTP protocols. Layer 7 routes HTTP by domain and URL. The wrong layer means rebuilding the architecture, not editing one line.
No. Add backend nodes sideways for the new traffic. The entry and the policy stay. After the peak, remove nodes from the group to control cost.
Deploy the new version to part of the group and send it a small share first. When it is stable, increase the share. On a problem, send all traffic back to the old nodes. Rollback does not redeploy.
Node count equals peak concurrency divided by the per-node connection tier, rounded up, plus 1 spare. At 5,000 peak connections and 1,000 per node, that is 5 plus 1 spare, 6 nodes. At 2,000 per node, it is 3 plus 1. Fill the tier from a real single-machine test. max_conns defaults to 0, which means no limit.
The check is usually too strict. One failure inside a 10 second window pulls a node out during a brief network blip, then puts it back. Raise the failure count to 2 or 3, and stretch the window to 10 or 15 seconds. After recovery, turn on slow start so weight climbs from zero instead of taking a full burst at once. A group with only one node ignores the failure count, so keep at least two nodes if removal should work.
Layer 4 forwards the TCP connection and does not rewrite the payload, so the backend sees the entry as the source. For the real client address, Layer 7 adds X-Forwarded-For or X-Real-IP and the application logs that header. Layer 4 needs PROXY protocol on both the entry and the backend. Do not rate-limit on the entry IP alone, or every user looks like one source.
Long connections, WebSocket, and database protocols should use Layer 4 and stay as TCP. Layer 7 fits short HTTP requests that split by domain and URL. If the Layer 7 idle timeout is shorter than the keepalive, the entry closes the connection. Keep sticky sessions on, or later packets from the same connection can land on another node.